About this document
 To the extent possible under law, the authors have waived all
copyright and related or neighboring rights to this document. For details,
please refer to the Creative Commons
CC0 license 2.
This work is published from: CERN, Geneva.
Introduction
This introductory text is non-normative. Sections of this chapter that are non-normative are marked as such; all other sections are normative.
It is widely agreed upon that the publication of likelihood models from high energy physics experiments is imperative for the preservation and public access to these results. Detailed arguments have been made elsewhere already 3. This document sets out to provide a standardized format to publish and archive statistical models of any size and across a wide range of mathematical formalisms in a way that is readable by both humans and machines.
With the introduction of pyhf 45, a JSON format for likelihood serialization has been put forward. However, an interoperable format that encompasses likelihoods with a scope beyond stacks of binned histograms was lacking. With the release of ROOT 6.26/00 6 and the experimental RooJSONFactoryWSTool therein, this gap has now been filled.
This document sets out to document the syntax and features of the Statistics Serialization Standard (HS\({}^3\)) for likelihoods and statistical models in general, as to be adopted by any HS\({}^3\)-compatible statistics framework. The examples in this document employ the JSON notation, but are intended to encompass also representations as YAML or TOML.
How to use this document
This section is non-normative.
Developers of statistical toolkits are invited to specifically refer to versions of this document relating to the support of this standard in their respective implementations.
Please note that this document as well as the HS\({}^3\) standard are still in development and can still undergo minor and major changes in the future. This document describes the syntax of HS\({}^3\) version 0.3. Documents conforming to this version identify themselves with "hs3_version": "0.3" (see Metadata).
Statistical semantics of HS\({}^3\)
Statistical models, probability distributions and parameters
HS\({}^3\) takes a "forward-modelling" approach throughout: a statistical model \(m\) maps a space \(\Theta\) of free parameters \(\theta\) to a space of probability distributions that describe the possible outcomes of a specific experiment. For any given parameters \(\theta\), the model returns a concrete probability distribution \(m(\theta)\). Observed data \(x\) is then treated as random variate, presumed to be drawn from the model: \(x \sim m(\theta)\). Parameters in HS\({}^3\) are always named, so semantically the elements of a parameter space \(\Theta\) are records \(\theta\) (i.e. tuples in which every entry has a name). Even if there is only a single free parameter, \(\theta\) should be thought of as a single-entry record. In the current version of this standard, parameter tuples must be flat and only consist of real numbers (or strings for categorical parameters); vector-valued or nested entries are not supported yet. Future versions of the standard will likely be less restrictive, especially with respect to discrete or vector-valued parameters. Parameter domains defined as part of this standard may be of various types, even though the current version only supports product domains. Future versions are likely to be less restrictive in this regard. Mathematically and computationally, it is often convenient to treat parameters as flat real-valued vectors instead of records, it is the responsibility of the implementation to map between these different views of parameters when and where necessary. Probability distributions in HS\({}^3\) (see Distributions) are typically parameterized. Any instance of a distribution that has some of its parameters bound to names instead of concrete values, e.g. \(m = d_{\mu = a, \sigma = 0.7, \lambda = b, ...}\), constitutes a valid statistical model \(m(\theta)\) with model parameters \(\theta = (a, b)\). When probability distributions are combined via a Cartesian product (see Product distribution), then the records that contain their free parameter values are concatenated. So \(m = d_{\mu = a, \sigma = b} \times d_{\mu = c, \sigma = 0.7}\) constitutes a model \(m(\theta)\) with model parameters \(\theta = (a, b, c)\). Distribution parameters may also be bound to the output of functions, and if those functions have inputs that are bound to names instead of values (or again bound to such functions, recursively), then those names become part of the model parameters. A configuration \(m = d_{\mu = a, \sigma = 0.7, \lambda = f}, f = \texttt{sum}(4.2, g), g = \texttt{sum}(1.3, b)\), for example, also constitutes a (different) model \(m(\theta)\) with parameters \(\theta = (a, b, c)\). If all parameter values of a probability distribution are set to concrete values, so if there are not directly (or indirectly via functions) bound to names, we call this probability distribution a concrete distribution here. Such distributions can be used as Bayesian priors (see Bayesian inference).
The variates of all distributions (so the possible results of random draws from them) are currently always records (this may be relaxed in future versions of this standard). So even instances of univariate distributions, like the normal distribution, have variates structured like \((a = \ldots,)\). Individual names are assigned to each entry of such record-valued variates.
Future versions of the standard may support array-shaped and record-of-arrays-shaped variates and parameters.
Global namespace
The names of all named HS\({}^3\) objects (distributions, functions, likelihoods, data, parameters, variables, domains, parameter points, etc.) form a single namespace and must be unique within an HS\({}^3\) document. The names assigned to variate record entries and data fields/axes are not part of the global namespace. Neither are the names of analyses (see Analyses): the names of analyses must be unique among all analyses in an HS\({}^3\) document, but an analysis may have the same name as an object in the global namespace, for example the likelihood it refers to. Future versions of this standard may restrict the latter.
Only the definition of a named object introduces a name into the global namespace. Places where a name is merely used to refer to an existing object do not introduce a new name. In particular, the entries of parameters in a parameter point (see Parameter points) refer to parameters of the model rather than defining new named objects, so the same parameter name may appear in several parameter points without violating the uniqueness requirement.
HS\({}^3\) implementations will typically provide a renaming/aliasing mechanism that can be used to resolve name clashes when using multiple HS\({}^3\) documents together, e.g. for combined analyses.
Identifiers
The names of HS\({}^3\) objects that can be referenced from generic expressions, i.e. parameters, variables, functions and distributions, must be identifiers matching the regular expression [A-Za-z_][A-Za-z0-9_]*: an ASCII letter or underscore, followed by any number of ASCII letters, digits or underscores. The generic expression language (see Generic Expressions) relies on this, since symbols in an expression that are not defined by the expression language refer to these objects by name, and names containing other characters could not be written there without an escaping mechanism.
The names of data sets, likelihoods, analyses, domains and parameter points should follow the same rule, but are not required to.
Probability density functions (PDFs)
Statistics literature often discriminates between probability density functions (PDF) for continuous probability distributions and probability mass functions (PMF) for discrete probability distributions. This standard use the term PDF for both continuous and discrete distributions. The concept of density is to be understood in terms of densities in the realm of measure theory here, that is the density of a probability measure (distribution) is its Radon-Nikodym derivative in respect to an (implied) reference measure. The choice of reference measure would be arbitrary in principle, which scales likelihood functions (Sec. Likelihood) by a constant factor that depends on choice of reference. In this standard, a specific reference measures is implied for each probability distribution, typically the Lebesgue measure for continuous distributions and the counting measure for discrete distributions. The standard aims to match the PDF (resp. PMF) most commonly used in literature for each specific probability distribution and the mathematical form of the PDF is documented explicitly for each distribution in the standard. So within HS\({}^3\), probability densities and likelihood functions are unambiguous. Here we use \(\text{PDF}(m(\theta), x)\) to denote the density value of the probability distribution/measure \(m\), parameterized by \(\theta\), at the point/variate \(x\), in respect to the implied reference for \(m\).
Observed and simulated data
The term data refers here to any collection of values that represents the outcome of an experiment. Data takes the same form as variates of distributions (see Distributions, i. e. a record of real values or vectors. To compare given data with a given model, the names and shapes of the data entries must match the variates of the probability distributions \(m(\theta)\) that the model returns for a specific choice of parameters \(\theta\). This means that given a model \(m\) and concrete parameter values \(\theta\), drawing a set of random values from the probability distribution \(m(\theta)\) produces a valid set of simulated observations. Implementations can use this to provide mock-data generation capabilities.
Likelihood functions
The concrete probability distribution \(m(\theta)\) that a model \(m\) returns for specific parameter values \(\theta\) can be compared to observed data \(x\). This gives rise to a likelihood \(\mathcal{L}_{m,x}(\theta) = \text{PDF}(m(\theta), x)\) that is a real-valued function on the parameter space. Multiple distributions/models that describe different modes of observation can be combined with multiple sets of data that cover those modes of observation into a single likelihood (Sec. Likelihoods). In addition to using observed data, implementations may provide the option to use random data generated from the model (see Data) to check for Monte-Carlo closure.
Frequentist parameter inference
This section is non-normative.
The standard method of frequentist inference is the maximum (or, respectively, profile) likelihood method. In the vast majority of cases, the test statistic used here is the likelihood ratio, that is, the ratio of two values of the likelihood corresponding to two different points in parameter space: one that maximizes the likelihood unconditionally, and one that maximizes the likelihood under some condition such as the values of the parameters of interest expected in the absence of a deviation from the null hypothesis. The corresponding building blocks for such an analysis, such as the list of parameters of interest and the likelihood function to be used, are specified in the analysis section of an HS\({}^3\) configuration (Sec. Analyses).
Bayesian parameter inference
This section is non-normative.
The standard also encompasses the specification of Bayesian posterior distributions over parameters by combining (Sec. Analyses) likelihoods with probabilty distributions that acts the priors. Here concrete distributions are used to describe the prior probability of parameters in addition to parameterized distributions that are used to describe of the probability of observing specific data.
How to read this document
In the context of this document, any JSON object is referred to as a struct. A key-value-pair inside such a struct is referred to as a component. If not explicitly stated otherwise, all components mentioned are mandatory.
The components located inside the top-level struct are referred to as top-level components.
The keywords must, must not, required, should, should not, may and optional are used in accordance with IETF requirement levels 7.
Terms and Types
This is a list of used types and terms in this document.
struct: represented with { }, containing a key:value mapping, keys are of typestring.component: key-value pair within a structarrayarray of items (eitherstrings ornumbers) without keys. Represented with[...].string: references to objects, names and arbitrary information. Represented with"..."number: either floating or integer type valuesboolean: boolean values; they can be encoded astrueandfalse
All structs defining functions, distributions, parameters, variables, domains, likelihoods, data or parameter points will be referred to as objects. All objects must always have a component name. These names are subject to the uniqueness rule given in Global namespace.
Within most top-level components, any one string given as a value to any component should refer to the name of another object, unless explicitly stated otherwise. Top-level components in which this is not the case are explicitly marked as such.
File format
HS\({}^3\) documents are encoded in the JSON format as defined in ISO/IEC 21778:2017 8. Implementations may support other serialization formats that support a non-ambiguous mapping to JSON, such as TOML or YAML, in which case they should use a different file extension.
An HS\({}^3\) document that contains a JSON object with two or more members of the same name is invalid. All numeric values must be finite IEEE-754 double-precision numbers that are representable as JSON numbers; the non-standard literals NaN, Infinity and -Infinity must not be used.
The recommended filename extension for HS\({}^3\) JSON documents is .hs3.json.
Validators
This section is non-normative.
Future versions of this standard will recommend official validator implementations and schemata. Currently, these have not been finalized.
How to get in touch
This section is non-normative.
Visit the GitHub page https://github.com/hep-statistics-serialization-standard/hep-statistics-serialization-standard
Top-level components
In the following, the top-level components of HS\(^3\) and their parameters/arguments are described. Each component is completely optional, but certain components may depend on other components, which should be provided in that case. The only exception is the component metadata containing the version of HS\(^3\), which is always required. The supported top-level components are
distributions: (optional) array ofobjects defining distributionsfunctions: (optional) array ofobjects defining mathematical functionsdata: (optional) array ofobjectsdefining observed or simulated datalikelihoods: (optional) array ofobjects defining combinations of distributions and datadomains: (optional) array ofobjects defining domains, describing ranges of parametersparameter_points: (optional) array ofobjects defining parameter points. These may be used as starting points for minimizations or to document best-fit-values or nominal truth values of datasetsanalyses: (optional) array ofobjects defining suggested analyses to be run on the models in this filemetadata: required struct containing meta information; HS\(^3\) version number (required), authors, paper references, package versions, data/analysis descriptions (optional)misc: (optional) struct containing miscellaneous information, e.g. optimizer settings, plotting colors, etc.
In the following each of these are described in more detail with respect to their own structure.
Distributions
The top-level component distributions contains an array of distributions in struct format. Distributions must be normalized, thus, the letter \(\ensuremath{\mathcal{M}}\) in the following descriptions will always relate to the normalization of the distribution. The value of \(\ensuremath{\mathcal{M}}\) is conditional on the current domain. It must be chosen such that the integral of the distribution over the current domain equals one. The implementations might chose to perform this integral using analytical or numerical means.
Each distribution must have the components type, denoting the kind of distribution described, and a component name, which acts as a unique identifier of this distribution among all other named objects. Distributions in general have the following keys:
name: custom unique string (required), e. g.my_distribution_of_xtype: string (required) that determines the kind of distribution, e. g.gaussian_dist...: each distribution may have components for the various individual parameters. For example, distributions of typegaussian_disthave the specific componentsmean,sigmaandx. In general, these components may be strings as references to otherobjects, but may also directly yield numeric or boolean values. Depending on the parameter and the type of distribution, they appear either in single item or array format.
An example for a two-dimensional multivariate distribution mvnormal1 that has two free parameters param_a and param_b and might be used as a forward model - and to construct a likelihood when combined with data that has fields/columns/axes obs_x and obs_y:
"distributions":[
    ...
    {
        "name": "mvnormal1",
        "type": "multivariate_normal_dist",
        "mean": ["param_a", "param_b"],
        "covariances": [[1.0, 0.3], [0.3, 2.0]],
    "x": ["obs_x", "obs_y"]
  },
    ...
]
An example of a distribution gauss1 that has no free parameters and might be used as a prior for a fit parameter param_a:
"distributions":[
    {
        "name":"gauss1",
        "type":"gaussian_dist",
        "mean": 4.2,
        "sigma": 1.0,
        "x":"param_a"
    },
    ...
]
Distributions can be treated either as extended or as non-extended 9. Some distributions are always extended, others can never be extended, yet others can be used in extended and non-extended scenarios and have a switch selecting between the two. An non-extended distribution is always normalized to the unity. An extended distribution, on the other hand, can yield values larger than unity, where the yield is interpreted as the number of predicted events. That is to say, the distribution is augmented by a factor that is a Poisson constraint term for the total number of events.
In the following, all distributions supported in HS\({}^3\) v0.2.9 are listed in detail. Future versions will expand upon this list.
Entries explicitly identified as current draft spellings document ongoing post-v0.2.9 work and have not yet been assigned to a new HS\({}^3\) version.
In Cartesian products of distributions, their variate records are concatenated.
Univariate fundamental distributions
This section contains univariate fundamental distributions in the sense that they cannot refer to any other distribution -- only to functions, parameters and exactly one variable.
Argus distribution
The Argus background distribution is defined as
and describes the ARGUS background shape.
name: custom unique stringtype:argus_distmass: name of the variable \(m\) used as massresonance: value or name of the parameter used as resonance \(m_0\)slope: value or name of the parameter used as slope \(c\)power: value or name of the parameter used as exponent \(p\).
Continued Poisson distribution
The continued Poisson distribution of the variable \(x\) is defined as
where \(\Gamma\) denotes the Euler Gamma function.
This function is similar to the Poisson distribution (see Poisson distribution{reference-type="ref" reference="dist:poisson"}), but can accept non-integer values for \(x\). Notably, the differences between the two might be significant for small values of \(x\) (below \(1\)). Nevertheless, the distribution is useful to deal with datasets with non-integer event counts, such as Asimov datasets 10.
name: custom unique stringtype:poisson_distx: name of the variable \(x\) (usually referred to as \(k\) for the standard integer case)mean: value or name of the parameter used as mean \(\lambda\).
Chebychev distribution
The Chebychev distribution is defined as a polynomial in Chebychev polynomials of the first kind:
The coefficient of the constant term \(T_0(z)=1\) is implicit and fixed to one.
name: custom unique stringtype:chebychev_distx: name of the variable \(x\)coefficients: array of coefficients \(a_i\) for the non-constant Chebychev terms. The first coefficient belongs to \(T_1(z)\).
Uniform distribution
The continuous uniform distribution is defined as:
name: custom unique stringtype:uniform_distx: name of the variable \(x\)
Crystal Ball distribution
The single-sided Crystal Ball line shape, composed of a Gaussian distribution at the core, connected with a power-law distribution describing one of the tails, given by
where \(t = \frac{m - m_0}{\sigma}\) if \(\alpha > 0\) and \(t = -\frac{m - m_0}{\sigma}\) if \(\alpha < 0\), and
For \(\alpha > 0\) the power-law tail is on the low side of \(m_0\), for \(\alpha < 0\) it is on the high side of \(m_0\).
The keys are
name: custom stringtype:crystalball_distm: name of the variable \(m\)m0: name or value of the central value \(m_0\)sigma: value or name of the width \(\sigma\)alpha: value or name of \(\alpha\)n: value or name of \(n\)
The keys alpha_L, n_L, alpha_R, n_R, sigma_L and sigma_R must not be present. For a Crystal Ball distribution with two tails, see the double-sided Crystal Ball distribution below.
{
  "name": "cb",
  "type": "crystalball_dist",
  "m": "mass",
  "m0": "mass_peak",
  "sigma": "mass_width",
  "alpha": 1.5,
  "n": 3.0
}
Double-sided Crystal Ball distribution
The generalized Asymmetrical Double-Sided Crystal Ball line shape, composed of a Gaussian distribution at the core, connected with two power-law distributions describing the lower and upper tails, given by
where
The keys are
name: custom stringtype:crystalball_doublesided_distm: name of the variable \(m\)m0: name or value of the central value \(m_0\)alpha_L,n_L: values or names of \(\alpha_L\) and \(n_L\)alpha_R,n_R: values or names of \(\alpha_R\) and \(n_R\)sigma: value or name of \(\sigma = \sigma_L = \sigma_R\). must not be used in conjunction withsigma_Lorsigma_R.sigma_L,sigma_R: values or names of \(\sigma_L\) and \(\sigma_R\). must not be used in conjunction withsigma.
All four of alpha_L, n_L, alpha_R and n_R must be present. The width must be given either as sigma or as both sigma_L and sigma_R. The keys alpha and n must not be present. There is no shorthand for symmetric tails: a symmetric double-sided Crystal Ball distribution is described by giving the same value, or referencing the same parameter, for both sides.
{
  "name": "cb_asym",
  "type": "crystalball_doublesided_dist",
  "m": "mass",
  "m0": "mass_peak",
  "sigma_L": "mass_width_L",
  "sigma_R": "mass_width_R",
  "alpha_L": 1.2,
  "n_L": 4.0,
  "alpha_R": 2.0,
  "n_R": 10.0
}
{
  "name": "cb_sym",
  "type": "crystalball_doublesided_dist",
  "m": "mass",
  "m0": "mass_peak",
  "sigma": "mass_width",
  "alpha_L": "cb_alpha",
  "n_L": "cb_n",
  "alpha_R": "cb_alpha",
  "n_R": "cb_n"
}
Backward compatibility. Documents conforming to versions of this standard before 0.3 may contain distributions of type crystalball_dist with the keys alpha_L, n_L, alpha_R and n_R (or sigma_L and sigma_R). Implementations should read these as crystalball_doublesided_dist; this is unambiguous from the key names. Documents conforming to version 0.3 or later must use crystalball_doublesided_dist for the double-sided form. Note that crystalball_dist with alpha and n is now defined as the single-sided Crystal Ball distribution, in line with how existing documents were written in practice; earlier versions of this text read it as the symmetric double-sided form.
Decay distribution
The decay distribution describes a single- or double-sided exponential decay convolved with a resolution model \(R\):
where
name: custom unique stringtype:decay_distt: name of the decay-time variable \(t\)tau: value or name of the decay constant \(\tau\)resolutionModel: name of the resolution model \(R\)decayType: integer selecting the decay basis, with0forSingleSided,1forDoubleSided, and2forFlipped.
Exponential distribution
The exponential distribution is defined as
name: custom unique stringtype:exponential_distx: name of the variable \(x\)c: value or name of the parameter used as coefficient \(c\).
Gaussian/normal distribution
The Gaussian/normal distribution is defined as
name: custom unique stringtype:gaussian_distornormal_distx: name of the variable \(x\)mean: value or name of the parameter used as mean value \(\mu\)sigma: value or name of the parameter encoding the standard deviation \(\sigma\).
Generalized Normal distribution
The generalized normal distribution is defined as
cf. the Wikipedia definition.
This form is of particular use with values of \(\beta \sim 8\) to generate a flat-topped distribution useful for "2 point" parameter-constraints between models where there is no clear preference but their average should not be particularly favoured. (In such usage, the template points should ideally be located at \(|x| < \pm 1\), to avoid disfavouring a pure solution.)
name: custom unique stringtype:generalized_normal_distx: name of the variable \(x\)mean: value or name of the parameter used as mean value \(\mu\)alpha: value or name of the \(\alpha\) parameter encoding the width; this corresponds to \(\sigma = \alpha/\sqrt{2}\) when \(\beta = 2\).beta: power \(\beta\) to which the exponent is raised, \(\beta = 2\) corresponding to the \(\text{GaussianPdf}\) shape.
Log-Normal distribution
The log-normal distribution is defined as
name: custom unique stringtype:lognormal_distx: name of the variable \(x\)mu: value or name of the parameter used as \(\mu\)sigma: value or name of the parameter \(\sigma\) describing the shape
Landau distribution
The Landau distribution describes fluctuations in the energy loss of a charged particle traversing a thin layer of material. In terms of the conventional Landau density \(L\), it is
name: custom unique stringtype:landau_distx: name of the variable \(x\)mean: value or name of the location parameter \(\mu\)sigma: value or name of the scale parameter \(\sigma\)
Poisson distribution
The Poisson distribution of the variable \(x\) is defined as
where \(x\) is required to be an integer. In this case, the behavior for non-integer values of \(x\) is undefined.
name: custom unique stringtype:poisson_distx: name of the variable \(x\) (usually referred to as \(k\) for the standard integer case)mean: value or name of the parameter used as mean \(\lambda\).
Polynomial distribution
The polynomial distribution is defined as
name: custom unique stringtype:polynomial_distx: name of the variable \(x\)coefficients: array of coefficients \(a_i\). The length of this array implies the degree of the polynomial.
Multivariate fundamental distributions
This section contains multivariate fundamental distributions. They may refer to functions, parameters and more than one variable.
Barlow-Beeston-Lite Constraint distribution
This distribution represents a product of Poisson distributions
defining the statistical uncertainties of the histogram templates
defined in a histfactory function.
name: custom unique stringtype:barlow_beeston_lite_poisson_constraint_distx: array of names of the variables \(x_i\). This also includes mixed arrays of values and names.expected: array of central values \(\tau_i\)
Multivariate normal distribution
The multivariate normal distribution is defined as
with \(\boldsymbol\Sigma \in \mathbb{R}^{k\times k}\) being positive-definite.
name: custom unique stringtype:multivariate_normal_distx: array of names of the variables \(\mathbf{x}\). This also includes mixed arrays of values and names.mean: array of length \(k\) of values or names of the parameters used as mean values \(\boldsymbol\mu\)covariances: an array comprised of \(k\) sub-arrays, each of which is also of length \(k\), designed to store values or names of the entries of the covariance matrix \(\boldsymbol\Sigma\). In general, the covariance matrix \(\boldsymbol\Sigma\) must be symmetric and positive-definite, so that its inverse \(\boldsymbol\Sigma^{-1}\) appearing in the density exists.
Generic distribution
Note: Users should prefer the specific distributions defined in this standard over generic distributions where possible, as implementations of these will typically be more optimized. Generic distributions should only be used if no equivalent specific distribution is defined.
A generic distribution is defined by an expression that represents the PDF of the distribution in respect to the Lebesgue measure. The expression must be a valid HS3-expression string (see Section Generic Expressions).
name: custom stringtype:generic_distexpression: a string with a generic mathematical expression. Simple mathematical syntax common to most programming languages should be used here, such asx-2*y+z. The argumentsx,yandzin this example must be parameters, functions or variables. The distribution is normalized by the implementation, so a normalization term should not be included in the expression. If the expression results in a negative value, the behavior is undefined.
HistFactory distribution
A HistFactory distribution is a joint probability distribution over bin counts \(n_i\), with independent Poisson probabilities whose expectations are supplied by a mixture of histogram templates. Its random variables are the bin counts, not the observable \(x\) used to define the fixed bins. The corresponding histfactory function (see Section Functions) provides the expected bin yields \(\lambda_i(\theta)\) from the sample mixture and its modifiers:
This probability mass function is normalized over nonnegative integer count vectors \(\mathbf{n}\). The parameters \(\theta\) may include both parameters of interest and nuisance parameters.
The prediction \(\lambda_i(\theta)\), the modifiers and their constraints, and an example are defined in Section HistFactory.
name: custom unique stringtype:histfactory_dist- all further components as defined in Section HistFactory
Relativistic Breit-Wigner distribution
The relativistic Breit-Wigner distribution describes the line shape of a resonance in the mass spectrum of a two-particle system. The resonance couples to a non-empty list of two-body channels. The first channel specifies the observed final state.
The variate \(m\) is the invariant (running) mass of the observed two-particle system. The parameter \(m_\text{BW}\) is the nominal mass of the resonance; it is not, in general, its pole mass. For \(m>m_{11}+m_{21}\), the density is
The density is zero below the observed-channel threshold. Values at the threshold itself are defined by the limit from above, when finite; an integrable endpoint singularity does not change the probability distribution. \(\mathcal{M}\) normalizes the density over the current domain. The parameters and domain must give a finite, strictly positive normalization integral.
The factor \(m\) in the numerator accounts for the Jacobian of the transformation from \(m^2\) to \(m\); its constant factor of two is absorbed in \(\mathcal{M}\). The factor \(\Gamma_1(m)\) includes the observed-channel phase space and angular-momentum dependence. This specifies a line-shape model without additional mass-dependent production factors or interference terms.
name: custom unique stringtype:relativistic_breit_wigner_distmass: name of the observable mass variable \(m\)resonance: value or name of the parameter \(m_\text{BW}\), the nominal masschannels: non-empty array of channel structs, with the observed channel first
The nominal mass must be strictly positive. For an open channel, the contribution is defined by
Here \(q_i(m)\) is the real, non-negative breakup momentum. If the evaluation range includes closed channels, use the analytic continuation described in the note below.
The Blatt-Weisskopf factors use the convention of Eqs. (50.33)-(50.34) in Ref. 11:
For completeness, the same convention for any non-negative integer \(l\) is fixed by the polynomials
Each channel struct contains:
name: name of the final state (optional)Gamma: value or name of the non-negative width coefficient \(\Gamma_{\text{BW},i}\), with units of mass; it is not generally the partial width at the nominal massm1: value or name of the non-negative mass \(m_{1i}\) of the first daughter (optional, default \(0\))m2: value or name of the non-negative mass \(m_{2i}\) of the second daughter (optional, default \(0\))l: non-negative integer orbital angular momentum \(l_i\) (optional, default \(0\))R: value or name of the strictly positive radius parameter \(R_i\), with units of inverse mass (optional, default \(3\,\mathrm{GeV}^{-1}\))
The first channel's Gamma must be strictly positive. Masses and width coefficients must use a common mass unit, and radii must use the corresponding inverse unit so that \(q_iR_i\) is dimensionless. The default radius is converted accordingly when masses are expressed in a unit other than GeV.
For a channel open at \(m_\text{BW}\), its partial width evaluated at the nominal mass is
The coefficient Gamma is therefore not generally equal to that partial width, even for \(l_i=0\). This definition retains the unnormalized phase-space and barrier factors; it does not use the nominal-partial-width convention of Eq. (50.35) in Ref. 11. No division by a phase-space factor at the nominal mass is made, so a channel may also have its threshold at or above \(m_\text{BW}\).
A constant-width special case is one channel with \(m_1=m_2=0\) and \(l=0\). For \(m>0\), \(q=m/2\), \(\rho=1\), and \(n_0^2=h_0^2=1\), giving \(\Gamma(m)=\Gamma_{\text{BW},1}\) independently of \(R\).
For example, a constant-width model with masses in GeV can be encoded as
{
  "name": "resonance_shape",
  "type": "relativistic_breit_wigner_dist",
  "mass": "m",
  "resonance": 1.0,
  "channels": [
    {"Gamma": 0.1, "m1": 0.0, "m2": 0.0, "l": 0}
  ]
}
Note on analytic continuation. A model with several channels may be evaluated in a mass range where the observed channel is open but some other channels are closed. Those channels still contribute to the denominator. When \(q_i^2(m)<0\), their breakup momentum is computed as \(q_i(m)=+i\sqrt{-q_i^2(m)}\), as in Eq. (50.36) of Ref. 11, and their \(\Gamma_i(m)\) can consequently be complex. These continued contributions must be retained, rather than set to zero; they are not physical decay widths below threshold.
The physical-sheet prescription, including the region below the pseudothreshold for unequal daughter masses, is
with principal square roots for real \(m>0\). Thus \(q_i\) is positive imaginary between \(|m_{1i}-m_{2i}|\) and \(m_{1i}+m_{2i}\), and negative real below \(|m_{1i}-m_{2i}|\). Values at \(m=0\), if needed as a domain endpoint, are taken as limits from above. The rational barrier factors are continued as written: neither \(h_l^2(z)\) nor \(n_{l_i i}^2(m)\) denotes a modulus squared for complex arguments. Removable singularities of the complete line shape are evaluated by continuity. The observed-channel numerator is used only above its own threshold, where it is real and non-negative; the density remains zero below that threshold.
Composite distributions
This section contains composite distributions in the sense that they refer to other distribution which they combine or modify in some way.
Mixture distribution
The mixture distribution, sometimes called addition of distributions, is a (weighted) sum of distributions \(f_i(\vec{x})\), depending on the same variable(s) \(\vec{x}\):
where the \(c_i\) are coefficients and \(\vec{x}\) is the vector of variables.
name: custom unique stringtype:mixture_distx: name of the variable \(x\) (optional, since the variable is fully defined by the summands)summands: array of names referencing distributionscoefficients: array of names of coefficients \(c_i\) or numbers to be addedextended: boolean denoting whether this is an extended distribution (optional, as it can be inferred from the lengths of the lists forsummandsandcoefficients) This distribution can be treated as extended or as non-extended.- If the number of coefficients equals the number of distributions and
extendedisfalse, then the sum of the coefficient must be (approximately) one. - If the number of coefficients equals the number of distributions and
extendedistrue, then the sum of the coefficients will be used as the Poisson rate parameter and the mixture distribution itself will use the coefficients normalized by their sum. - If the number of coefficients is one less than the number of distributions, then
extendedmust befalseand \(c_n\) is computed from the other coefficients as
Mixture model
The mixture model is a weighted sum of resolution models or model PDFs:
If one coefficient fewer than the number of summands is provided, the final coefficient is computed as
If all coefficients are given, their sum is used as the expected number of events in extended use cases.
name: custom unique stringtype:mixture_modelsummands: array of names referencing model distributionscoefficients: array of names of coefficients \(c_i\) or numbersextended: boolean denoting whether this is an extended model
Product distribution
The product of independent distributions \(f_i\) is defined as
name: custom stringtype:product_distx: name of the variable \(x\) (optional, since the variable is fully defined by the factors)factors: array of names referencing distributions
Efficiency product distribution
The efficiency product distribution multiplies a normalized PDF with an efficiency function and normalizes the product:
The efficiency function is expected to be non-negative over the domain.
name: custom unique stringtype:efficiency_product_pdf_distpdf: name of the input distribution \(f\)eff: name of the efficiency function \(\epsilon\)
Density Function distribution
A distribution that is specified via a non-normalized density function \(f(x)\). Formally, it corresponds to the probability measure that has the density \(f(x)\) in respect to the Lebesgue measure.
The density function is normalized automatically by \(\ensuremath{\mathcal{M}}= \int f(x) dx\), so the PDF of the distribution is
The distribution can be specified either via the non-normalized density function \(f(x)\) or via the non-normalized log-density function \(\log(f(x))\):
density_function_dist: Specified via the PDF \(f(x)\)name: custom stringtype:density_function_distfunction: The density function \(f\)
log_density_function_dist: Specified via the log-density \(\log(f(x))\)name: custom stringtype:log_density_function_distfunction: The logarithm \(\log f\) of the non-normalized density function \(f\)
Array distribution
The Array distribution is a product of \(n\) independent, one-dimensional distributions of one type, each over its own named observable:
where \(x_i\) is the observable named by x of the \(i\)-th entry of components and \(p_{i,1},\cdots,p_{i,k}\) are the \(k\) type-specific parameters of \(m\) assigned in that entry or in default_parameters. The observables \(x_i\) must be pairwise distinct. It is semantically equivalent to a Product distribution of \(n\) one-dimensional distributions of the given type, but declared flat and explicit such that engines may use a dedicated, vectorized implementation. Unlike an array of separate distributions, one draw from an Array distribution contains every component, and its evaluation returns one joint density.
An Array distribution is a struct defined by the following components:
name: custom unique stringtype:array_distcomponent_type:typeof the distribution \(m\) shared by all components. This determines the parameters that must be specified for each component, either in its entry ofcomponentsor indefault_parameterscomponents: array of structs, one per component of the product, each with:x: name of the observable \(x_i\). No two entries ofcomponentsmay name the same observable.- the parameters \(p_{i,j}\) of the distribution \(m\), each assigned to a number or name. If at least one parameter of at least one component is omitted here, the top-level component
default_parametersbecomes required and a default must be declared for that parameter. default_parameters: (optional) struct assigning parameters \(p_{i,j}\) of the distribution \(m\) to a number or name, applied to every component that does not specify them on its own
Names given in components or default_parameters must resolve to either a data set axis, parameter or function.
The parameters \(p_{i,j}\) must not depend, directly or through functions, on any observable \(x_k\) of the same Array distribution; they may share model parameters between components. Distinct observable names alone do not make the factors independent, and a dependence between them would leave the product unnormalized.
The typical usage, shown below, pairs the observables named by x with the axes of one unbinned data set holding auxiliary-measurement data for the constraint, with one axis per component and a single entry.
{
    "distributions":[
        ...
            {
                "name":"gauss_constraints",
                "type":"array_dist",
                "component_type":"gaussian_dist",
                "default_parameters":{"sigma":"gaussian_constraints_sigma"},
                "components":[
                    {"x":"nom_np_1", "mean":"np_1", "sigma":"np_1_sigma"},
                    {"x":"nom_np_2", "mean":"np_2"},
                    {"x":"nom_np_3", "mean":"np_3", "sigma":31.622}
                ]
            }
        ...
    ],
    "data":[
        ...
        {
            "name":"nom_np",
            "type":"unbinned",
            "entries":[[0, 0, 0]],
            "axes":[
                {"name":"nom_np_1", "min":-5, "max":5},
                {"name":"nom_np_2", "min":-5, "max":5},
                {"name":"nom_np_3", "min":-5, "max":5}
            ]
        }
        ...
    ]
}
{
    "distributions":[
        ...
            {
                "name":"poisson_constraints",
                "type":"array_dist",
                "component_type":"poisson_dist",
                "default_parameters":{"mean":"lambda_poisson"},
                "components":[
                    {"x":"nom_np_1", "mean":"lambda_1"},
                    {"x":"nom_np_2"}
                ]
            }
        ...
    ],
    "functions":[
        {
            "name":"lambda_1",
            "type":"product",
            "factors":[20.0, "np_1"]
        },
        {
            "name":"lambda_poisson",
            "type":"product",
            "factors":[10.0, "np_poisson"]
        }
    ],
    "data":[
        ...
        {
            "name":"nom_np",
            "type":"unbinned",
            "entries":[[20, 10]],
            "axes":[
                {"name":"nom_np_1", "min":0, "max":100},
                {"name":"nom_np_2", "min":0, "max":100}
            ]
        }
        ...
    ]
}
Poisson point process
A Poisson point process distribution is understood here as the distribution of the outcomes of a (typically inhomogeneous) Poisson point process. In particle physics, such a distribution is often called an extended distribution 9. In HS3, a Poisson point process distribution is specified using a global-rate parameter \(\lambda\) and an underlying distribution \(m\), either explicitly or implicitly (see below). Random values are drawn from the Poisson point process distribution by drawing a random number \(n\) from a Poisson distribution of the global-rate \(\lambda\), and then drawing \(n\) random values from the underlying distribution \(m\). The resulting random values are vectors \(x\) of length \(n\), so their length varies. The PDF the Poisson point process distribution at an outcome \(x\) (a vector of length \(n\)) is
In particle physics, the function \(\text{PoissonPointProcessPdf}(\lambda, m(\theta), x)\), for a fixed observation \(x\) and varying parameters \(\lambda\) and \(\theta\), is often called an extended likelihood. A Poisson point process distribution can be specified in HS3 in two ways:
rate_extended_dist: The global-rate parameter \(\lambda\) and underlying distribution \(m\) are specified explicitly:name: custom stringtype:rate_extended_distrate: The global rate \(\lambda\)dist: The underlying distribution \(m\)
The name of the variable \(x\) is taken from the underlying distribution. The underlying distribution must not be referred to from other components of the statistical model.
rate_density_dist: Specified via a non-normalized rate-density function \(f\). Both the global-rate parameter and the underlying distribution are implicit: \(\lambda = \int f(y) d y\) and \(m = \text{DensityFunctionPdf}(f)\). More formally, the distribution corresponds to the inhomogeneous Poisson point process that is defined by a non-normalized rate measure which has density \(f\) in respect to the Lebesgue measure.name: custom stringtype:rate_density_distx: name of the variable \(x\)density: The rate-density function \(f\)
Bin-count distribution
This is a binned version of the Poisson point process distribution (Poisson point process). It is the distribution of the bin counts that result from histogramming the outcomes of a Poisson point process distribution using a given binning scheme (see Binned Data). Like the Poisson point process distribution, a Bin-counts distribution can either be specified via a global-rate parameter \(\lambda\) and an underlying distribution \(m\), or via a rate-density function \(f\) (in which case \(\lambda\) and \(m\) are implicit). In addition, the binning scheme also has to be specified in either case, unless it can be inferred (see below). For \(k\) bins, this type of distribution corresponds to a product of \(k\) Poisson distributions with rates
The PDF of the bin-counts distribution at an outcome \(x\) (a vector of length \(k\), same as the number of bins) is
-
bincounts_extended_dist: The global-rate parameter \(\lambda\) and underlying distribution \(m\) are specified explicitly:name: custom stringtype:bincounts_extended_distrate: The global rate \(\lambda\)dist: The underlying distribution \(m\)axes: a definition of the binning to be used, following the definitions in Binned Data. optional ifdistis a binned distribution, in which case the same binning is used by default.
The name of the variable \(x\) is taken from the underlying distribution. The underlying distribution must not be referred to from other components of the statistical model.
-
bincounts_density_dist: Specified via a non-normalized rate-density function \(f\). Both the global-rate parameter and the underlying distribution are implicit: \(\lambda = \int f(y) dy\) and \(m = \text{DensityFunctionPdf}(f)\).name: custom stringtype:bincounts_density_distx: name of the variable \(x\)density: The rate-density function \(f\)axes: a definition of the binning to be used, following the definitions in Binned Data.
More formally, the distribution corresponds to the inhomogeneous Poisson point process that is defined by a non-normalized rate measure which has density \(f\) in respect to the Lebesgue measure.
Functions
The top-level component functions describes an array of mathematical functions in struct format to be used as helper objects. Similar to distributions each entry is required to have the components type and name. Other components are dependent on the kind of functions. The field name is required and may be any custom unique string. Functions in general have the following components:
name: custom unique stringtype: string that determines the kind of function, e.g.sum...: each function has individual parameter keys for the various individual parameters. For example, functions of typesumhave the parameter keysummands. In general, these keys can describe strings as references to other objects or numbers. Depending on the parameter and the type of function, they appear either in single item or array format.
"functions": [
    {
        "name" : "sum1",
        "type" : "sum",
        "summands" : [1.8, 4, "param_xy"]
    },
    ...
]
In the following the implemented functions are described in detail.
Product
A product of values or functions \(a_i\).
name: custom unique stringtype:productfactors: array of names of the elements of the product or numbers.
Sum
A sum of values or functions \(a_i\).
name: custom unique stringtype:sumsummands: array of names of the elements of the sum or numbers.
Polynomial Function
The polynomial function is defined as
Unlike polynomial_dist, this object is a function and is not normalized.
name: custom unique stringtype:polynomialx: name of the variable \(x\)coefficients: array of coefficients \(a_i\). The length of this array implies the degree of the polynomial.
Derivative Function
The derivative function represents a numerical derivative of another function with respect to a variable:
The order is intended for first, second, or third derivatives, and eps controls the finite-difference step size.
name: custom unique stringtype:derivativefunction: name of the function \(f\)x: name of the differentiation variable \(x\)order: derivative order \(n\)eps: step size used for the numerical derivativenormalization: array of names defining the normalization set (optional)
Gaussian Resolution Model
The Gaussian resolution model represents a Gaussian smearing model in the convolution variable \(x\):
It can be used as a resolution model for analytical convolutions.
name: custom unique stringtype:gauss_model_functionx: name of the convolution variable \(x\)mean: value or name of the mean parameter \(\mu\)sigma: value or name of the width parameter \(\sigma\)
Truth Resolution Model
The truth resolution model corresponds to perfect resolution, represented by a delta function in the convolution variable:
When used in an analytical convolution, it returns the unconvolved basis function.
name: custom unique stringtype:truth_model_functionx: name of the convolution variable \(x\)
Integral Function
The integral function represents the integral of a function \(f\) over one or more variables:
If domain is present, the integral uses the named domain for the integration variables. If normalization is present, the integrand is evaluated with that normalization set.
name: custom unique stringtype:integralintegrand: name of the function \(f\) to integratevariables: array of names of the integration variables \(\vec{x}\)domain: name of the integration domain (optional)normalization: array of names defining the normalization set (optional)
HistFactory Function
A HistFactory function provides the expected counts in fixed bins of an observable \(x\) by adding sample histogram yields with their modifiers (normalization factors, systematic variations, statistical uncertainties). It is the deterministic prediction component of the HistFactory model:
Here \(i\) labels a fixed bin in \(x\); \(\theta\) controls the sample yields and shapes. The corresponding histfactory_dist uses these expectations to model the random bin counts \(n_i\). The mixture interpretation, parameter roles, modifiers and example are defined in Section HistFactory.
name: custom unique stringtype:histfactory- all further components as defined in Section HistFactory
Generic Function
Note: Users should prefer the specific functions defined in this standard over generic functions where possible, as implementations of these will typically be more optimized. Generic functions should only be used if no equivalent specific distribution is defined. A generic function is defined by an expression. The expression must be a valid HS3-expression string (see Section Generic Expressions).
name: custom unique stringtype:generic(current draft spelling;generic_functionis the legacy HS\({}^3\) v0.2.9 key)expression: a string with a generic mathematical expression. Simple mathematical syntax common to programming languages should be used here, such asx-2*y+z. For any non-elementary operations, the behavior is undefined.
Data
The top-level component data contains an array of data sets in struct format. Each data set needs to contain the components type and name. Other components are dependent on the type of data set as demonstrated below:
name: custom stringtype: string that determines the format of the observations...: each type of observations has different parameter keys. Some of these are optional and marked accordingly in the more detailed description below
A detailed description of the different types with examples can be found below. While data, in most settings, has no uncertainty attached to it, this standard does allow to provide data with uncertainty, as there are some settings in which uncorrelated or correlated errors need to be taken into account. These include cases such as
- generated data obtained from importance sampling, including a (potentially Gaussian) uncertainty from the frequency weights
- unfolded data, resulting from arbitrarily complex transformation functions involving statistical models folding some degree of uncertainty into the data points themselves
While it should always be preferred to publish "raw" data, allowing to include pre-processed data with corresponding uncertainties expands the possible applications considerably.
Axis Specifications
Axes define the observable domain for data and PDFs. Every axis is either continuous or categorical. The kind of an axis is determined structurally: an axis struct must contain exactly one of the field pair min/max (continuous axis) or the field categories (categorical axis). Continuous axes additionally have type-specific requirements based on the data type they describe.
Continuous Axes
A continuous axis describes a real-valued observable. All continuous axes must include:
name: identifier matching the observable in the PDFmin: lower bound of the observable domainmax: upper bound of the observable domain
These fields define the domain over which PDFs are normalized.
Note on normalization: Any PDF depending on a continuous observable \(x\) must be normalized over the domain \([\text{min}, \text{max}]\) defined by that observable's axis, not over \((-\infty, \infty)\).
Categorical Axes
A categorical axis describes a discrete-valued observable that takes one of a finite set of named states. A categorical axis must include:
name: identifier matching the categorical observable in the PDFcategories: array of unique strings enumerating the allowed values.categoriesdefines a set: the order in which values appear in the array must not affect evaluation.
The categories array itself defines the domain of the axis; the fields min, max, nbins and edges must not be present.
Forbidden Attributes
The const attribute must not appear in axis specifications. All axes define observable domains, never fit parameters.
Axis Types by Data Type
For Point Data:
- Only continuous axes are permitted, carrying only the base fields (
name,min,max) - Binning fields (
nbins,edges) must not be present
For Unbinned Data:
- Continuous axes are required to carry base fields (
name,min,max) - Binning fields (
nbins,edges) must not be present - Categorical axes are permitted; the corresponding column of
entriesholds the respective row's category as one of the strings listed incategories
For Binned Data:
- Continuous axes are required to carry base fields (
name,min,max) - Each continuous axis must carry exactly one binning specification:
- Regular binning:
nbins(integer number of equal-width bins) - Irregular binning:
edges(array of length \(n+1\) bin boundaries)
- Regular binning:
- Both
nbinsandedgesmust not be specified simultaneously - Neither
nbinsnoredgesmust not be omitted on a continuous axis - Categorical axes are permitted. A categorical axis acts as its own binning, with one bin per category in the order given by
categories
For irregular binning, the edges array must satisfy:
- edges[0] == min
- edges[-1] == max
- All values must be in strictly ascending order
Point Data
Point data describes a measurement of a single number, with a possible uncertainty (error).
name: custom stringtype:pointvalue: value of this data pointaxes: (optional) array of axis structs. Each struct must containname,min,maxas defined in Axis Specifications. When present, associates the point measurement with a specific observable domain.uncertainty: (optional) uncertainty of this data point
"data":[
    {
        "name":"data1",
        "type":"point",
        "value":0.,
        "uncertainty":1.,
        "axes":[
            { "name":"obs_x", "min":-5, "max":5 }
        ]
    }
]
Unbinned Data
Unbinned data describes a measurement of multiple data points in a possibly multi-dimensional space of variables. These data points can be weighted.
name: custom stringtype:unbinnedentries: array of arrays containing the coordinates/entries of the dataaxes: array of axis structs. Each struct must be a valid continuous or categorical axis as defined in Axis Specifications. Binning fields (nbins,edges) must not be present.weights: (optional) array of values containing the weights of the individual data points, to be used for \(\chi^2\) comparisons and fits. If this component is not given, weight 1 is assumed for all data points. If given, the array needs to be of the same length asentries.entries_uncertainties: (optional) array of arrays containing the errors/uncertainties of each entry. If given, the array needs to be of the same shape asentries.
"data":[
  {
    "name":"data1",
    "type":"unbinned",
    "weights":[ 9.0, 18.4 ],
    "entries":[ [1,3], [2,9] ],
    "entries_uncertainties":[ [0.3], [0.6] ],
    "axes":[
      { "name":"variable1", "min":1, "max":3 },
      { "name":"variable2", "min":-10, "max":10 }
    ]
  }
]
entries:
"data":[
  {
    "name":"data2",
    "type":"unbinned",
    "weights":[12.0, 4.3, 2.1],
    "entries":[["SR",7,0.1], ["SR",9,-0.2], ["CR",4,0.9]],
    "axes":[
      {"name":"cat1", "categories":["SR","CR"]},
      {"name":"variable1", "min":3, "max":20},
      {"name":"variable2", "min":-1, "max":1}
    ]
  }
]
entries refers to the cat1 axis, giving the category of each row directly as "SR" or "CR".
Binned Data
Binned data describes a histogram of data points with bin contents in a possibly multi-dimensional space of variables. Whether entries that fall precisely on the bin boundaries are sorted into the smaller or larger bin is under the discretion of the creator of the model and thus not defined.
name: custom stringtype:binnedcontents: array of values representing the contents of the binned data setaxes: array of axis structs. Each struct must be a valid continuous or categorical axis as defined in Axis Specifications. Each continuous axis must carry exactly one binning specification:- Regular binning:
nbins(number of equal-width bins) - Irregular binning:
edges(array of length \(n+1\) bin boundaries)
- Regular binning:
uncertainty: (optional) struct representing the uncertainty of the contents. It consists of up to three components:type: denoting the kind of uncertainty, for now only Gaussian distributed uncertainties denoted asgaussian_uncertaintyare supportedsigma: array of the standard deviation of the entries incontents. Needs to be of the same length ascontentscorrelation: (optional) array of arrays denoting the correlation between the contents in matrix format. Must be of dimension length ofcontents\(\times\) length ofcontents. It can also be set to 0 to indicate no correlation.
"data":[
  {
    "name":"data3",
    "type":"binned",
    "contents":[ 9.0, 18.4 ],
    "axes":[ { "name":"variable1", "nbins":2, "min":1, "max":3 } ]
  },
  {
    "name":"asimov_data3",
    "type":"binned",
    "contents":[ 9.0, 18.4, 13, 0. ],
    "axes":[
      { "name":"variable1", "nbins":2, "min":1, "max":3 },
      { "name":"variable2", "min":0, "max":100, "edges":[0,10,100] }
    ]
  }
]
The contents of the data sets are represented in a flattened one-dimensional array of bin-contents. Here the behaviour is the same for a categorical axis with \(n\) categories as for regularly-binned continuous axis with \(n\) bins: each category corresponds to one bin along the respective dimension of the flattened contents array.
"data":[
  {
    "name":"data4",
    "type":"binned",
    "content":[9.0, 8.4, 4.0, 7.0],
    "axes":[
      {"name":"channel", "categories":["SR","CR"]},
      {"name":"variables1", "nbins":2, "min":0, "max":10}
    ]
  }
]
This type can also be used to store pre-processed data utilizing the uncertainty component
"data":[
  {
    "name":"data5",
    "type":"binned",
    "contents":[ 9.0, 18.4 ],
    "uncertainty" : {
      "type": "gaussian_uncertainty",
      "correlation" : 0,
      "sigma" : [ 3, 4 ]
     },
    "axes":[
      { "name":"variable1", "nbins":2, "min":1, "max":3 }
    ]
  }
]
Likelihoods
The top-level component likelihoods contains an array of likelihoods in struct format specifying mappings of distributions and observations. The corresponding distributions and observations are inserted as keys in string format referencing to distributions and observations defined in the respective top-level components, or as numbers for fixed data values.
The combination of parameterized distributions \(m_i(\theta_i)\) with observations \(x_i\) generates a likelihood function
The components of a likelihood struct are:
name: custom stringdistributions: array of strings referencing the considered distributionsdata: array of strings referencing the used data, must be of the same length as the array ofdistributions. Alternatively, the data-values for single-dimensional distributions can be given in-line. For example, this can be used for constraint terms representing auxiliary measurements.aux_distributions: (optional) array of strings referencing the considered auxiliary distributions defined in the top-level componentdistributions. They can be used to encode regularizers or penalty terms to aid the minimization. These observed data for these distributions is implicit and not part ofdata.
"likelihoods":[
  {
    "name":"likelihood1",
    "distributions":[
      "dist1",
      "dist2",
      "single_dimensional_dist_1",
      ...
    ],
    "data":         [
      "data1",
      "data2",
      0,
      ...
    ],
    "aux_distributions" : [ "regularization_term" ]
  },
  ...
]
Encoding of auxiliary measurements and global observables is discussed in Auxiliary measurements.
Domains
The top-level component domains contains an array of domains giving information on the ranges of parameters and variables in struct format. Within a specified domain, the corresponding model is expected to yield valid values. Each domain must contain a name and a type although right now only the product_domain type is supported, even though others like e. g. a simplex domain might be added later. A domain consists of the following components:
name: custom stringtype:product_domainaxes: array of parameters and variables in this domain in terms of individual axes. These can be continuous or categorical, mirroring the axis types defined in Axis Specifications.- A continuous axis has the components:
name: custom stringmax: (optional) upper bound of range. If absent, the range is unbounded from above (\(+\infty\)).min: (optional) lower bound of range. If absent, the range is unbounded from below (\(-\infty\)).nbins: (optional) number of equal-width bins of the default binning of this parameter or variableedges: (optional) array of bin boundaries of the default binning of this parameter or variable
- A categorical axis has the components:
name: custom stringcategories: array of unique strings enumerating the allowed values
- A continuous axis has the components:
An axis is categorical if and only if it contains the component categories; otherwise it is continuous. A continuous axis should contain at least one of min and max. An axis with neither is valid and places no restriction on the range of the parameter; it still counts as listing the parameter in the domain (see Analyses). Since JSON has no literal for infinity, omitting min or max is the only way to express an unbounded range.
The components nbins and edges specify a default binning, e.g. for plotting or for binned evaluation by an implementation that requires one. They have the same meaning and are subject to the same constraints as on continuous axes of binned data (see Binned Data and Axis Specifications): nbins and edges must not both be present, either of them requires both min and max to be present, and with edges, min and max must be equal to the first and last entry of edges, respectively. Categorical axes must not carry nbins or edges.
"domains":[
  {
    "name":"domain1",
    "type":"product_domain",
    "axes": [
      { "name" : "par_1", "min" : 1, "max" : 8 },
      { "name" : "par_2", "min" : 4.78, "max" : 6 },
      { "name" : "par_3", "min" : 0 },
      { "name" : "obs_x", "min" : 0, "max" : 10, "nbins" : 20 },
      { "name" : "obs_y", "min" : 0, "max" : 10, "edges" : [0, 1, 2, 5, 10] },
      { "name" : "channel", "categories": ["SR","CR"] },
      ...
    ]
  },
  ...
]
Parameter points
The top-level component parameter_points contains an array of parameter configurations. These can be starting values for minimizations, parameter settings used to generate toy data, best-fit-values obtained, or points in parameter space used for different purposes.
name: custom stringparameters: array of parameter structs (see below) The componentparametersis an array of structs, each of which assigns a value to one parameter of the model. Thenameof such an entry refers to that parameter; it does not define a new named object. Consequently, the same parameter may appear in any number of parameter points (see Global namespace). Each entry contains:name: name of the parameter this entry refers tovalue: value of the parameter: a number, or a string for a categorical parameter. A string value must be one of thecategoriesof a categorical axis of the same name in the domain(s) the parameter point is used with, e.g. thedomainsof an analysis that references it asinit(see Domains).const: (optional) boolean, whether variable is constant or not. Default isfalse.
"parameter_points":[
  {
    "name" : "starting_values",
    "parameters": [
      { "name" : "par_1", "value": 3 },
      { "name" : "par_2", "value": 7, "const": true },
      { "name" : "channel", "value": "SR" },
      ...
     ]
  },
  ...
]
Analyses
The top-level component analyses contains an array of possible (automated) analyses. To that extent, likelihoods, parameters of interest and the affiliated domains are listed. Description of the components:
name: long custom stringlikelihood: name as reference to a likelihood defined in the top-level componentlikelihoodsparameters_of_interest: (optional) array of names as reference to parameters that are interesting for the analysis at handdomains: array of names of domains to be used for the parameters, defined in the top-level componentdomains. The effective domain of the analysis is the Cartesian product of the listed domains. If two of the listed domains contain an axis with the same name, the document is invalid.init: (optional) name of an initial value to be used, defined in the top-level componentparameter_pointsprior: (optional) name of a prior distribution, defined in the top-level componentdistributions. This is only used for Bayesian interpretations and should not be confused with auxiliary distributions listed in the likelihood section. The prior could, for example, be a product distribution of all the individual priors. If for any parameter, both a prior and a parameter domain are given, the prior should be truncated to the given parameter domain. Otherwise, implicit flat priors over the given parameter domain are assumed.
All parameters of all distributions in the likelihood must either be listed in one of the domains referenced, or set to const in the parameter point referenced.
"analyses": [
  {
    "name" : "analysis1",
    "likelihood" : "likelihood1",
    "parameters_of_interest" : ["param1"],
    "domains" : ["domain1"],
    "init" : "starting_values",
    "prior" : "prior_dist"
  },
  ...
]
Metadata
The top-level component metadata contains meta-information related to the creation of the file. The component hs3_version stores the HS\(^3\) version and is required for now. Overview of the components:
hs3_version: (required) string identifying the version of HS\(^3\) the document conforms to, in the form"MAJOR.MINOR", whereMAJORandMINORare non-negative integers in decimal notation without leading zeros (e.g."0.3"). The value is a JSON string, not a number. Revisions of this document that do not change what constitutes a valid HS\(^3\) document do not change the version string; there is no patch-level component.packages: (optional) array of structs defining packages and their version number used in the creation of this file, depicted with the componentsnameandversionrespectivelyauthors: (optional) array of authors, either individual persons, or collaborationspublications: (optional) array of document identifiers of publications associated with this filedescription: (optional) short abstract/description for this file
"metadata" : {
  "hs3_version" : "0.3",
  "packages" : [ { "name": "ROOT", "version": "6.28.02" } ],
  "authors": ["The ATLAS Collaboration", "The CMS Collaboration"],
  "publications": ["doiABCDEFG"]
}
Miscellaneous
The top-level component misc can contain arbitrary, user-created information in struct format.
"misc" : {
  "customkey1" : "custom information 1" ,
  "myPackage_internal" : {
    "somekey" : "custom info only affecting myPackage",
    "default_color_for_all_curves" : "fuchsia" }
  }
This top-level component is intended to store any and all additional information, including user- or backend-specific meta-information. Examples include, but are not limited to:
- colors and styles for drawing distributions in this file
- suggested settings for samplers or minimizers when working with the distributions in this file
- comments explaining design choices made when building the model in this file
- suggested names and paths for output files to be used by backends working with this file
Supplementary Material
This section contains supplementary material referenced in section [sec:toplevel]
Generic Expressions
This section details the HS\({}^3\) generic expression language. Expressions can be use to specify generic functions and generic distributions. The implementations that support generic expression must support:
- Literal integer (format
1234), boolean (formatTRUEandFALSE) and floating point (format123.4,1.234e2and1.234E2) values. - Literal values for \(\pi\) (
PI) and Euler's number (EULER). - The arithmetic operators addition (
x + y), subtraction (x - y), multiplication (x * y), division (x / y) and exponentiation (x^y). - The comparison operators approximately-equal (
x == y), exactly-equal (x === y), not-approximately-equal (x != y), not-exactly-equal (x !== y), less-than (x < y), less-or-equal (x <= y), greater-than (x > y) and greater-or-equal (x >= y). - The logical operators logical-inverse (
!a), logical-and (a && b) and logical-or (a || b). - Round brackets to specify the order of operations.
- The conditional expression
ifelse(condition, result_if_true, result_if_false). - The functions
exp(x): Euler's number raised to the power ofxlog(x): Natural logarithm ofxsqrt(x): The square root ofxabs(x): The absolute value ofxfloor(x): The greatest integer less than or equal toxceil(x): The smallest integer greater than or equal toxpow(x, y):xraised to the power ofymin(x, y): minimum ofxandymax(x, y): maximum ofxandysin(x): The sine ofxcos(x): The cosine ofxtan(x): The tangent ofxasin(x): The inverse sin ofxacos(x): The inverse cosine ofxatan(x): The inverse tangent ofxerf(x): The standard error function ofx
Symbols not defined here refer to variables in the HS\({}^3\) model.
The operator precedence and associativity is according to the common conventions.
Spaces between operators and operands are optional. There must be no space between a function name and the function arguments, spaces between function arguments are optional (f(a, b) and f(a,b) are correct but f (a, b) is not allowed).
Division must be treated as floating-point division (i.e. 2/3 should be equivalent to 2.0/3.0).
The approximately-equal (a == b) and the not-approximately-equal operator (a != b), should compare floating-point numbers to within a small multiple of the unit of least precision.
Conditional expression may be evaluated in a lazy fashion (evaluating either result_if_true or result_if_false depending on the result of condition) or in an eager fashion (evaluating all of condition, result_if_true and result_if_false in arbitrary order). Evaluation strategy is left to the engine. This implies that on some engines, large trees of conditional expressions may have a high evaluation cost.
The behavior of any functions and operators not listed above is not defined, they are reserved for future versions of this standard. Implementations may support additional functions and operators as experimental features, but their use is considered non-standard and results in non-portable and potentially non-forward-compatible HS\({}^3\) documents.
Authoring Requirements for HS\(^3\) Primitive Specifications
Primitive specifications define the mathematical semantics of new HS\(^3\) primitives. Their purpose is to enable independent implementations to interpret serialized models consistently and without ambiguity.
Intended audience
Primitive specifications should be understandable to three audiences simultaneously:
- Software implementers, who should be able to implement import, export, and evaluation directly from the specification.
- Domain experts, who should recognize how concepts from existing software correspond to the HS\(^3\) representation.
- Statisticians, who should be able to infer the mathematical properties of the primitive directly from its specification and serialized representation.
The mathematical definition is normative. Implementation-specific terminology may be used where it improves understanding, but should complement rather than replace the mathematical semantics.
Design principles
A primitive specifies what a model computes, not how a particular implementation computes it.
Specifications shall therefore define primitives in mathematical terms whenever practical. Implementation-specific concepts may be included only where they are necessary to faithfully represent existing software.
A primitive that introduces functionality which cannot already be represented using existing HS\(^3\) primitives will generally be appropriate, provided its semantics are well defined.
A primitive that only specializes an existing abstraction should provide clear additional value, such as a substantially more compact representation of a common use case, access to significantly more efficient or numerically robust evaluation strategies, or improved interoperability through the explicit representation of a widely recognized abstraction.
Relationship to the HS\(^3\) language
Primitive specifications extend the vocabulary of HS\(^3\) but do not redefine the language itself.
Primitive specifications may introduce new functions, distributions, or regular members of any other existing top-level HS\(^3\) category (see Section Top-level components). They shall not introduce new language constructs. In particular, a primitive shall not change its semantic role based on configuration or context, create or transform other serialized objects, or introduce control-flow, parser directives, or other metaprogramming facilities. Such proposals constitute extensions of the HS\(^3\) language and require separate specification and review.
Required specification
Every primitive specification shall define:
- its mathematical semantics, or an equivalent algorithmic definition;
- the meaning of every serialized field, including the relationship between serialized objects and the mathematical quantities they represent;
- any normative default values;
- sufficient examples to remove ambiguity.
Primitive specifications should define the normative semantics of a primitive independently of any particular implementation. Whenever practical, this should be done by specifying the mathematical object represented by the primitive. Where no sufficiently precise mathematical characterization exists, or where the algorithm itself defines the abstraction, a normative algorithmic specification may be used instead.
The amount of explanatory material should be proportional to the complexity of the primitive. Simple primitives may require little more than their mathematical definition and serialization. More complex primitives should include whatever additional explanation is necessary to enable independent conforming implementations. Informative mappings to existing software are encouraged but never replace the normative definition.
Serialization
Every serialized field shall have a well-defined mathematical meaning.
Serialized objects should expose mathematical structure wherever practical. Mathematical concepts such as coefficients, tensors, domains, or observables should be preferred over implementation-specific concepts such as object handles or memory layouts.
Implementation-specific state may be serialized where necessary, but should remain self-contained, inspectable, schema-validatable, and editable whenever practical. References to external binary objects should be avoided unless no practical alternative exists.
Defaults and miscellaneous information
Evaluation shall be completely determined by the serialized object together with any normative defaults defined by the primitive.
Optional fields that affect evaluation shall have unique specification-defined default values. Such defaults shall not depend on implementations, external libraries, software versions, or backend-specific conventions.
Information that has no effect on mathematical evaluation shall be stored in misc. Conforming evaluators shall produce equivalent results regardless of the contents of misc, although implementations may use it for diagnostics, visualization, optimization, or internal representation.
Existing implementations
Where a primitive represents functionality already established in an existing framework or scientific domain, its semantics should remain recognizable to domain experts while preserving implementation-independent mathematical meaning.
Primitive specifications should minimize the conceptual distance between established domain abstractions and their HS\(^3\) representation. Generalization is appropriate where it improves interoperability or removes accidental implementation details. It should be avoided where it obscures established abstractions or complicates import, export, or implementation without providing corresponding semantic benefit.
Alternative implementations
An enum-like field may select between alternative methods when those methods operate on the same serialized state and the meaning of all other fields remains unchanged. The selected method may alter how that state is interpreted or evaluated, but shall not determine which disjoint set of fields is applicable.
If different enum values require substantially different configuration data, parameterizations, or validity conditions, they should generally be represented as separate primitives rather than as variants of a single primitive.
Implementations need to support only a subset of the methods defined by a primitive specification. An implementation that does not support the requested method shall not silently substitute another method. It shall either reject the object or explicitly report the use of a semantically valid fallback.
Conformance
A primitive specification is complete if independent implementations can reproduce equivalent mathematical behaviour from the specification alone, together with the documentation of any explicitly referenced external libraries.
Normative text defines behaviour. Informative text may provide motivation, examples, implementation guidance, historical context, or mappings to existing software, but does not contribute to the formal definition of the primitive.
Editorial Guideline
As a practical guideline, contributors should continuously ask:
Could an independent, faithful implementation of this primitive be written without ambiguity from this specification alone, together with the documentation of any explicitly referenced external libraries?
If the answer is no, the specification is likely missing semantic or algorithmic information.
HistFactory
HistFactory, documented by Cranmer et al. in 2012 12, models bin counts as independent Poisson random variables whose expectations come from a mixture of histogram templates. Its random variables are the counts \(n_i\); \(x\) is the observable (or tuple of observables) used to define the fixed bins \(B_i\).
A channel is a selected event category or analysis region with its own observed histogram, such as a signal or background control region. Each prediction adds the contributions of samples (signal and background processes) sharing the channel's binning. Parameter variations change yields, not bin boundaries; different channels may use different binning.
The sample yields and normalized shapes define the event intensity:
Each sample has a yield \(N_s\) and a normalized shape \(f_s\) over the channel's observable region. The intensity integrates to the total expected yield \(\sum_s N_s\), rather than to one. HistFactory stores bin yields directly; the decomposition into yields and normalized shapes is explanatory. The parameters \(\theta\) may include both parameters of interest, such as a signal strength, and nuisance parameters describing uncertainties.
The function histfactory evaluates the expected bin yields \(\lambda_i(\theta)\). The distribution histfactory_dist additionally specifies the observation model
normalized over count vectors. Independence and Poisson fluctuations are modeling assumptions beyond the expected-yield prediction. Both representations use the samples, modifiers and constraint terms described below; their type entries differ. Figure 1 illustrates the sample contributions (originally from 13).
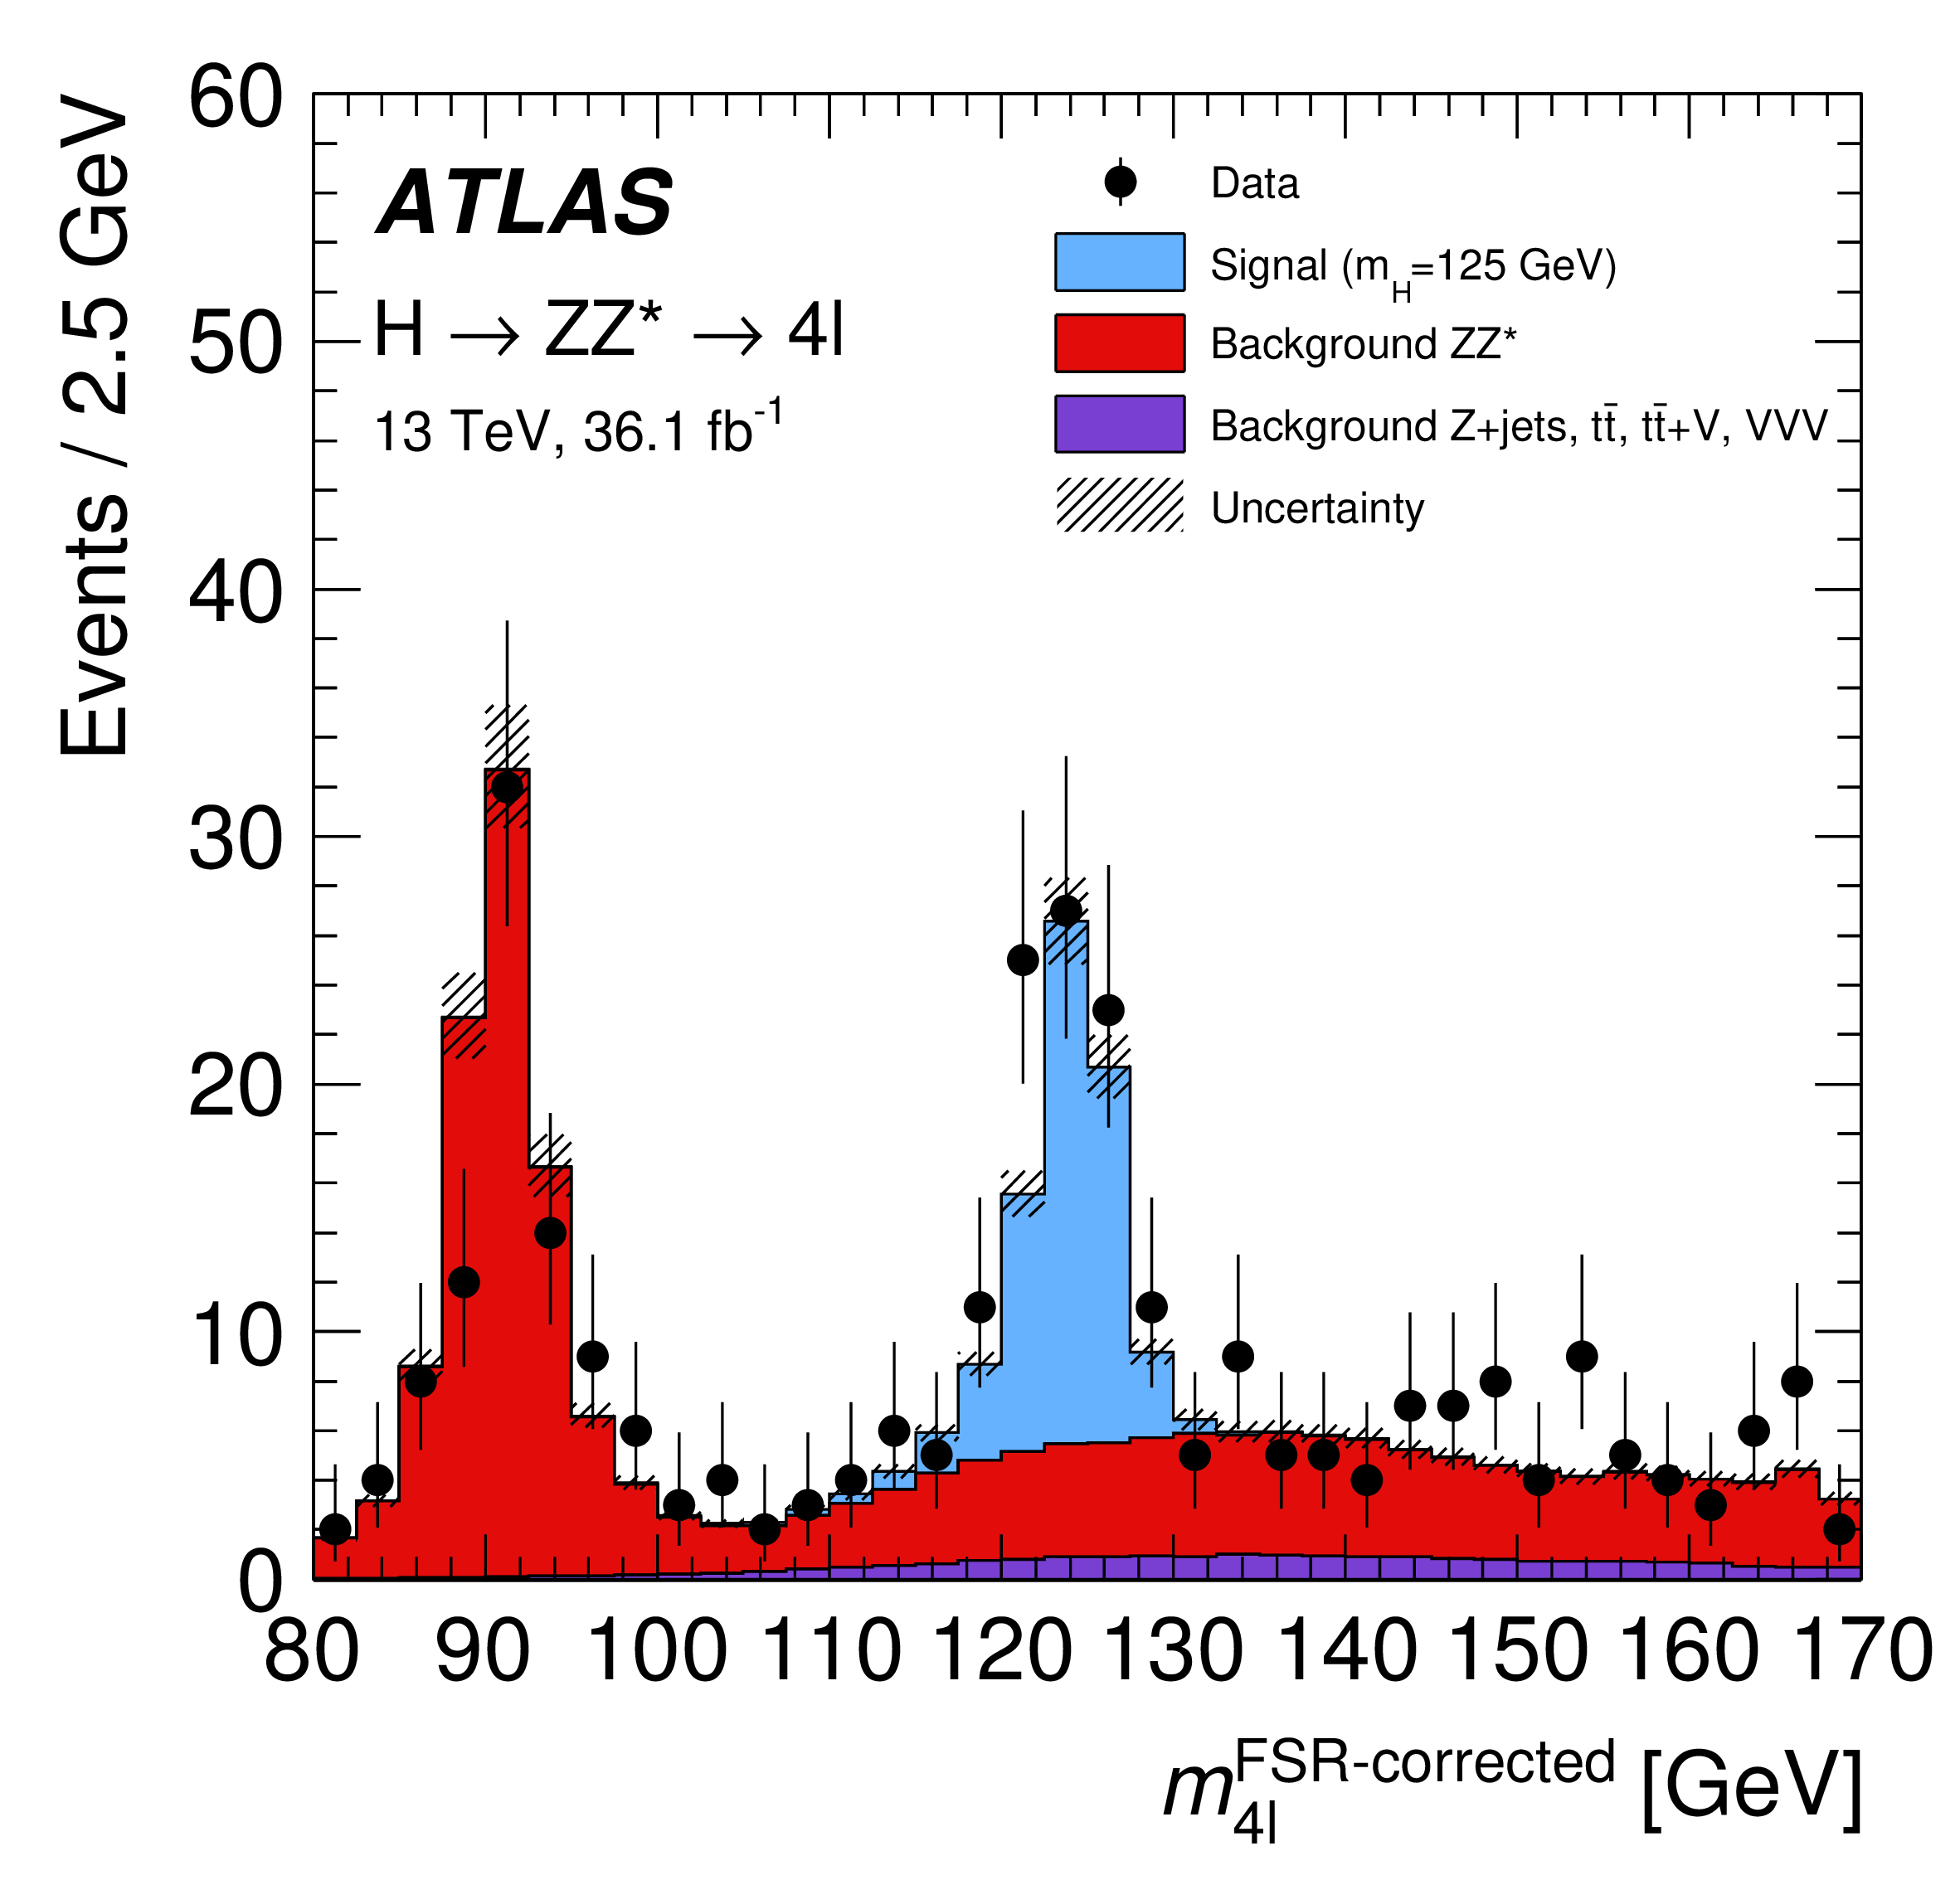
In the modifier formula below, \(\lambda(x)\) is a step function whose value in \(B_i\) is the bin yield \(\lambda_i(\theta)\). For continuous bins of width or volume \(|B_i|\), the corresponding piecewise-constant intensity is \(\rho(x;\theta)=\lambda_i(\theta)/|B_i|\); integrating \(\lambda(x)\) itself would incorrectly introduce a bin-volume factor.
Here \(d_s(x)\) is the prediction associated with the sample \(s\), a step function
In this section, \(\chi^{y_s}_{b}(x)\) denotes a generic step function in the binning \(b\) such that \(\chi_{b}(x) = y_{s,i}\), some constant, if \(x\in<span class="smallcaps">b_i,b_{i+1})\). The \(y_{s,i}\) in this case are the bin contents (yields) of the histograms. The \(M_\kappa\) are the multiplicative modifiers, the \(M_\delta\) are the additive modifiers. Each of the modifiers is either multiplicative (\(\kappa\)) or additive (\(\delta\)). All samples and modifiers share the same binning \(b\). The modifiers depend on the model parameters \(\theta\). Each modifier can only depend on one \(\theta_i\), but the \(\theta_i\) can take the form of vectors and the same \(\theta_i\) can be shared by several modifiers. By convention, these are denoted \(\alpha\) if they affect all bins in a correlated way, and \(\gamma\) if they affect only one bin at a time. The types of modifiers are
- A shape factor or
shapefactormodifier is a multiplicative modifier that scales each single bin by the value of an independent parameter \(\gamma\). Here, \(\theta_i=\vec{\gamma}\), where the length of \(\vec{\gamma}\) is equal to the number of bins in this region, andparametersholds one entry per bin. The parameters are constrained by the distributions named inconstraints, if given, and free otherwise; individual entries ofconstraints[may benull. shapesysis a deprecated alias ofshapefactor. Documents conforming to version 0.3 or later of this standard should not use it. Documents conforming to earlier versions may containshapesysmodifiers with bin-wise values indata.valsand a constraint type inconstraint; implementations should read these according to the version of the standard the document conforms to, as given byhs3_versionin its metadata.- A correlated shape systematic or
histosysmodifier is an additive modifier that adds or subtracts a constant step function \(\chi^f\), scaled with a single factor \(\alpha\). The modifier contains adatasection, which contains the subsections \(\texttt{hi}\) and \(\texttt{lo}\) that help to define the step function \(\chi^f\). They containcontents, which define the bin-wise additions or subtractions for \(\alpha=1\). The functional form of \(\chi^f\) for intermediate and outlying \(\alpha\) is set by theinterpolationcomponent, described below. Here, \(\theta_i=\alpha\). - A normalization systematic or
normsysmodifier is a multiplicative modifier that scales the entire sample with the same constant factor \(f\) that is a function of \(\alpha\). The modifier contains adatasection, which contains the values \(\texttt{hi}\) and \(\texttt{lo}\) that help to define \(f\). There are different functional forms that can be chosen for \(f\). However, by convention \(f(\alpha=0)=1\), \(f(\alpha=+1)=\)"hi" and \(f(\alpha=-1)=\)"lo". The functional form of \(f\) for intermediate and outlying \(\alpha\) is set by theinterpolationcomponent, described below. In this case, \(\theta_i=\alpha\). - A normalization factor or
normfactormodifier is a multiplicative modifier that scales the entire sample in this region with the value of the parameter \(\mu\) itself. In this case, \(\theta_i=\mu\). - The
staterrormodifier is a shorthand for encoding uncorrelated statistical uncertainties on the values of the step-functions, using a variant1 of the Barlow-Beeston Method 14. It acts as ashapefactorwhose per-bin relative uncertainty is derived from the samples: \(\delta_i=\sqrt{\sum_s \sigma_{s,i}^2}\,/\sum_s y_{s,i}\), with \(y_{s,i}\) and \(\sigma_{s,i}\) thecontentsanderrorsof all samples in this region carrying astaterrormodifier. The distributions named inconstraintsshould be constructed as abarlow_beeston_lite_poisson_constraint_distwithxnaming the \(\gamma_i\) andexpectedholding \(\tau_i=\delta_i^{-2}\). Its parameters \(\vec{\gamma}\) are shared by all samples of the region that carry astaterrormodifier. - A
custommodifier is a multiplicative modifier that scales the sample with the value of an arbitrary function \(f\) defined in the top-level componentfunctions(see Functions). Thenameof the modifier is the name of \(f\). If \(f\) depends on the observables, it acts as a shape factor, otherwise as a normalization factor. Here, \(\theta_i\) are the parameters of \(f\); the componentsparameters,dataandconstraintsare not used for this type.
The different modifiers and their descriptions are also summarized in the following table:
| Type of Modifier | Description | Definition | Free Parameters | Number of Free Parameters |
|---|---|---|---|---|
histosys |
Correlated Shape systematic | \(\delta(x,\alpha) = \alpha * \chi_b^f\) | \(\alpha\) | 1 |
normsys |
Normalization systematic | \(\kappa(x,\alpha) = f(\alpha)\) | \(\alpha\) | 1 |
normfactor |
Normalization factor | \(\kappa(x,\mu) = \mu\) | \(\mu\) | 1 |
shapefactor, staterror |
Shape factor | \(\kappa(x,\vec{\gamma}) = \chi_b^{\gamma}\) | \(\gamma_0\), ..., \(\gamma_n\) | #bins |
custom |
Custom function | \(\kappa(x,\vec{\theta}) = f(x,\vec{\theta})\) | parameters of \(f\) | #parameters of \(f\) |
The way modifiers affect the yield in the corresponding bin is subject to an interpolation function. The histosys and normsys modifiers thus allow for an additional component interpolation, a struct with the components
type: how the response combines with the sample prediction,addormult, for additive or multiplicative, respectively,in: the interpolating function used inside the bounds, \(|\theta|<1\),out: the extrapolating function used outside the bounds, \(|\theta|\geq1\), ifnullthe same function as for interpolation is used.
The final modified prediction \(y(\theta_1,\dots,\theta_n)\) is obtained by combining the sample's nominal prediction \(y_0\) with a normalized response function \(I(\theta; y_-, y_0, y_+)\) for each parameter \(\theta_i\). Unlike \(y\), \(I\) is anchored relative to \(y_0\) rather than to it directly, with the anchor values depending on the combination type:
- For
type="add": \(I(0) = 0\), \(I(+1) = y_+ - y_0\), \(I(-1) = y_- - y_0\) - For
type="mult": \(I(0) = 1\), \(I(+1) = y_+ / y_0\), \(I(-1) = y_- / y_0\)
For type="mult", the combined prediction follows as:
while for type="add" the combination follows as:
Here \(y_{i,-}\) and \(y_{i,+}\) denote the lo/hi variations associated with parameter \(\theta_i\); \(y_0\), the sample's nominal prediction, is shared across all parameters and enters only through the combination above, never through \(I\) itself.
The following functions are allowed for in and out:
poly1: linear functionpoly2: parabolic functionpoly6: degree-6 polynomialexp: exponential function
The choice of functions for in and out, together with the anchor conditions above and, where required, matching of first and second derivatives at the boundary (\(\left.\frac{\mathrm{d}I}{\mathrm{d}\theta}\right|_{\theta=\pm 1}\) and \(\left.\frac{\mathrm{d}^2I}{\mathrm{d}\theta}\right|_{\theta=\pm 1}\)), fixes all free parameters of the chosen functions except for \(\theta\) itself.
The following choices of \(I\) are often used and showcase the resulting functional forms for common combinations of type, in and out. Note that for type="mult", all interior and extrapolation terms are expressed as ratios \(y_\pm/y_0\) rather than raw \(y_\pm\), so that the anchor condition \(I(0)=1\) holds independent of \(y_0\); for type="add", terms are expressed as differences \(y_\pm - y_0\), consistent with the anchor \(I(0)=0\).
- additive, piecewise linear:
{"type":"add", "in":"poly1", "out":null}- with \(I_1(\theta; y_-, y_0, y_+) = \left\{ \begin{array}{ll} \theta\cdot(y_+ - y_0) & \theta\geq0 \\ \theta\cdot(y_0-y_-) & \theta<0\end{array}\right.\)
- multiplicative, piecewise exponential:
{"type":"mult", "in":"exp", "out":null}- with \(I_2(\theta; y_-, y_0, y_+) = \left\{ \begin{array}{ll} (y_+/y_0)^\theta & \theta\geq0 \\ (y_-/y_0)^{-\theta} & \theta<0 \end{array}\right.\)
- additive, quadratic interpolation and linear extrapolation
{"type":"add", "in":"poly2", "out":"poly1"}- with \(I_3(\theta; y_-, y_0, y_+) = \left\{\begin{array}{ll}(2s+d)\cdot(\theta - 1) + y_+ - y_0 & \theta > 1 \\ s\cdot\theta^2 +d\cdot\theta & |\theta|\leq 1 \\ -(2s-d)\cdot(\theta + 1) + y_- - y_0& \theta < -1\end{array}\right.\), where \(s=\tfrac12(y_+ + y_-) - y_0\) and \(d=\tfrac12 (y_+ - y_-)\)
- additive, polynomial (6th degree) interpolation and linear extrapolation
{"type":"add", "in":"poly6", "out":"poly1"}- with \(I_4(\theta; y_-, y_0, y_+) = \left\{\begin{array}{ll} \theta\cdot(y_+ - y_0) & \theta \geq 1 \\ \theta\cdot(S+\theta \cdot A (15+\theta^2\cdot(3\theta^2 -10))) & |\theta| < 1 \\ \theta\cdot(y_0 - y_-) & \theta \leq -1 \end{array}\right.\), where \(S=\tfrac12(y_+ - y_-)\) and \(A=\tfrac{1}{16}(y_+ + y_- -2y_0)\)
- multiplicative, polynomial (6th degree) interpolation and exponential extrapolation
{"type":"mult", "in":"poly6", "out":"exp"}- with \(I_5(\theta; y_-, y_0, y_+) = \left\{\begin{array}{ll} (y_+/y_0)^\theta & \theta\geq 1 \\ 1+\theta\cdot(a+\theta\cdot(b+\theta\cdot(c+\theta\cdot(d+\theta\cdot(e+\theta\cdot f)))))& |\theta|<1\\ (y_-/y_0)^{-\theta} & \theta\leq-1\end{array}\right.\), where: \(\begin{array}{l} a=\tfrac18(15A_0-7S_1+A_2) \\ b=\tfrac18(-24+24S_0-9A_1+S_2) \\ c=\tfrac14(-5A_0+5S_1-A_2) \\ d=\tfrac14(12-12S_0+7A_1-S_2) \\ e=\tfrac18(3A_0-3S_1+A_2) \\ f=\tfrac18(-8+8S_0-5A_1+S_2) \end{array}\), with \(u=y_+/y_0\), \(v=y_-/y_0\), \(\log t := \begin{cases}\log t & t>0\\0 & t\leq0\end{cases}\), and \(\begin{array}{l} S_0=\tfrac12(u+v) \quad A_0=\tfrac12(u-v) \\ S_1=\tfrac12(u\log u-v\log v) \quad A_1=\tfrac12(u\log u+v\log v) \\ S_2=\tfrac12(u\log^2 u+v\log^2 v) \quad A_2=\tfrac12(u\log^2 u-v\log^2 v) \end{array}\)
- multiplicative, polynomial (6th degree) interpolation and linear extrapolation
{"type":"mult", "in":"poly6", "out":"poly1"}- with \(I_6(\theta; y_-, y_0, y_+) = 1 + I_4(\theta; y_-/y_0, 1, y_+/y_0)\)
Modifiers can be constrained. This is indicated by the component constraints, which names one or more distributions defined in the top-level component distributions. These are typically of type gaussian_dist or poisson_dist, but any distribution type is allowed. In essence, the likelihood picks up a penalty term for changing a constrained parameter too far away from its nominal value. By convention, the nominal value is 0 for the parameters of histosys and normsys modifiers and 1 for those of all other types. Constraints on histosys and normsys parameters should be a gaussian_dist with mean 0 and sigma 1, such that \(\alpha=\pm1\) corresponds to the hi and lo variations.
The constraint terms belong to the prediction and not to its representation: a likelihood that contains a histfactory_dist, or a distribution that depends on a histfactory function, considers the constraint terms of all modifiers of that prediction in addition to the aux_likelihood section of the likelihood, in the same way for both representations.
The components of a HistFactory prediction are:
name: custom unique stringtype:histfactory(function) orhistfactory_dist(distribution)axes: array of binned axis structs as defined for binned data in Axis Specifications.default_interpolation: optional struct defining the default interpolation behaviour, for modifiers that do not specify it on their own. It has the componentstype,inandout, as described above.samples: array of structs containing the samples of this channel. For details see below. Struct of one sample:name: (optional) custom string, unique within this functiondata: struct containing the componentcontentsand the (optional) componenterrors, depicting the sample contents and their per-bin uncertainties. Both components are arrays with length equal to the number of bins. Iferrorsis absent, no per-bin uncertainty is associated with the sample. Thisdatais the template of the sample, i.e. the predicted yields and their uncertainties, not observed data.modifiers: array of structs with each struct containing the modifiers for this sample. Struct of one modifier:name: (optional) custom string, unique within this sample. required forcustommodifiers, where it names a function defined in the top-level componentfunctions.type: type of the modifierparameters: array of strings naming the parameters controlling this modifier.data: optional relevant data for modifier. Its format depends ontype, which is described above.constraints: optional array of distribution names, with one entry for each parameter inparameters. Individual entries may benull, leaving the corresponding parameter unconstrained.interpolation: optional struct defining how the effect of the modifier is calculated within and outside of the boundaries \(\theta=\pm 1\). It has the componentstype,inandoutas described above. If this is omitted here for at least one modifier the top-level componentdefault_interpolationbecomes required. Implementations must not assume a default interpolation of their own; a document in which a modifier omitsinterpolationand nodefault_interpolationis given is invalid and must be rejected.
For modifiers controlling a single parameter (histosys, normsys, normfactor), the arrays parameters and constraints hold a single entry each.
Two modifiers are correlated if and only if they share the same parameters as indicated by parameters. In such a case, they must share the same constraint term in constraints.
{
  "name": "myAnalysisChannel",
  "type": "histfactory_dist",
  "axes": [
    { "max": 1.0, "min": 0.0, "name": "myRegion", "nbins": 2 }
  ],
  "default_interpolation": { "type": "mult", "in": "poly6", "out": "exp" },
  "samples": [
    {
      "name": "mySignal",
      "data": { "contents": [ 0.5, 0.7 ], "errors": [ 0.1, 0.1 ] },
      "modifiers": [
        { "parameters": ["Lumi"], "type": "normfactor" },
        { "parameters": ["mu_signal_strength"], "type": "normfactor" },
        { "constraints": ["my_normalization_systematic_1_constraint"],
          "data": { "hi": 1.1, "lo": 0.9 },
          "parameters": ["my_normalization_systematic_1"],
          "type": "normsys" },
        { "constraints": ["gamma_stat_1_constraint", "gamma_stat_2_constraint"], "type": "staterror",
          "parameters": ["gamma_stat_1","gamma_stat_2"]},
        { "constraints": ["my_correlated_shape_systematic_1_constraint"], "type": "histosys",
          "data": {
            "hi": { "contents": [ -2.5, -3.1 ] },
            "lo": { "contents": [ 2.2, 3.7 ] }
           },
           "interpolation": { "type": "add", "in": "poly6", "out": "poly1" },
           "parameters": ["my_correlated_shape_systematic_1"] },
        { "constraints": ["my_shapesys_2_bin0_constraint", "my_shapesys_2_bin1_constraint"],
          "parameters": ["my_uncorrelated_shape_systematic_2_bin0", "my_uncorrelated_shape_systematic_2_bin1"],
          "type": "shapefactor" }
      ]
    },
    {
      "name": "myBackground",
      ...
   }
  ]
}
Auxiliary measurements and global observables
This section is non-normative.
Auxiliary measurements commonly constrain nuisance parameters through additional likelihood terms. Their observed values, sometimes known as global observables, can be fixed and are generally not part of the primary data. The mechanisms described in Likelihoods can already accommodate such terms in several ways. Both forms presented here are mathematically equivalent and differ only in presentation and verbosity.
Each constraint distribution can enter the likelihood directly, paired with a point data set:
{
  ...
  "distributions":[
    {
      "name":"gauss_constraint_alpha_1",
      "type":"gaussian_dist",
      "x":"nom_alpha_1",
      "sigma":1.0,
      "mean":"alpha_1"
    },
    {
      "name":"gauss_constraint_alpha_2",
      "type":"gaussian_dist",
      "x":"nom_alpha_2",
      "sigma":1.0,
      "mean":"alpha_2"
    },
    {
      "name":"gauss_constraint_alpha_3",
      "type":"gaussian_dist",
      "x":"nom_alpha_3",
      "sigma":1.0,
      "mean":"alpha_3"
    },
    ...
  ],
  "data":[
    {
      "name":"obs_nom_alpha_1",
      "type":"point",
      "value":0.0,
      "axes":[{"name":"nom_alpha_1","min":-5,"max":5}]
    },
    {
      "name":"obs_nom_alpha_2",
      "type":"point",
      "value":0.0,
      "axes":[{"name":"nom_alpha_2","min":-5,"max":5}]
    },
    {
      "name":"obs_nom_alpha_3",
      "type":"point",
      "value":0.0,
      "axes":[{"name":"nom_alpha_3","min":-5,"max":5}]
    },
    ...
  ],
  "likelihoods":[
    {
      "name":"likelihood1",
      "distributions":["channel1_pdf","gauss_constraint_alpha_1","gauss_constraint_alpha_2","gauss_constraint_alpha_3"],
      "data":["channel1_data","obs_nom_alpha_1","obs_nom_alpha_2","obs_nom_alpha_3"]
    }
  ]
}
For models with many constraints, listing one term per auxiliary measurement becomes lengthy.
When the constraint terms are independent and of the same kind (e.g. unit Gaussians or Poisson terms) they can instead be collected into a single pair: an unbinned data set with one continuous axis per auxiliary observable and a single entry holding the auxiliary-measurement values, paired with an Array distribution that evaluates one constraint term per axis:
{
  ...
  "distributions":[
    {
      "name":"gauss_constraints",
      "type":"array_dist",
      "component_type":"gaussian_dist",
      "default_parameters":{"sigma":1.0},
      "components":[
        {"x":"nom_alpha_1","mean":"alpha_1"},
        {"x":"nom_alpha_2","mean":"alpha_2"},
        {"x":"nom_alpha_3","mean":"alpha_3"}
      ]
    },
    ...
  ],
  "data":[
    {
      "name":"global_observables",
      "type":"unbinned",
      "entries":[[0.0, 0.0, 0.0]],
      "axes":[
        {"name":"nom_alpha_1", "min":-5, "max":5},
        {"name":"nom_alpha_2", "min":-5, "max":5},
        {"name":"nom_alpha_3", "min":-5, "max":5}
      ]
    },
    ...
  ],
  "likelihoods":[
    {
      "name":"likelihood1",
      "distributions":["channel1_pdf","gauss_constraints"],
      "data":["channel1_data", "global_observables"]
    }
  ]
}
The single entry of the unbinned data set contributes exactly one factor per component to the likelihood, so each constraint term enters exactly once. Encoding constraint terms as an array distribution paired with an unbinned data set is recommended over listing individual pairs as described above.
References
-
The variation consists of summarizing all contributions in the stack to a single contribution as far as treatment of the statistical uncertainties is concerned. ↩
-
Creative Commons. Cc0 license. URL: https://creativecommons.org/publicdomain/zero/1.0. ↩
-
Kyle Cranmer, Sabine Kraml, Harrison Prosper, Philip Bechtle, Florian Bernlochner, Itay M. Bloch, Enzo Canonero, Marcin Chrzaszcz, Andrea Coccaro, Jan Conrad, Glen Cowan, Matthew Feickert, Nahuel Ferreiro, Andrew Fowlie, Lukas A. Heinrich, Alexander Held, Thomas Kuhr, Anders Kvellestad, Maeve Madigan, Farvah Nazila Mahmoudi, Knut Dundas Morå, Mark S. Neubauer, Maurizio Pierini, Juan Rojo, Sezen Sekmen, Luca Silvestrini, Veronica Sanz, Giordon H. Stark, Riccardo Torre, Robert Thorne, Wolfgang Waltenberger, Nicholas Wardle, and Jonas Wittbrodt. Publishing statistical models: getting the most out of particle physics experiments. SciPost Physics, January 2022. URL: http://dx.doi.org/10.21468/SciPostPhys.12.1.037, doi:10.21468/scipostphys.12.1.037. ↩
-
Lukas Heinrich, Matthew Feickert, and Giordon Stark. Pyhf. URL: https://github.com/scikit-hep/pyhf/releases/tag/v0.7.0, doi:10.5281/zenodo.1169739. ↩
-
Lukas Heinrich, Matthew Feickert, Giordon Stark, and Kyle Cranmer. Pyhf: pure-python implementation of histfactory statistical models. Journal of Open Source Software, 6(58):2823, 2021. URL: https://doi.org/10.21105/joss.02823, doi:10.21105/joss.02823. ↩
-
The ROOT Team. Root-project/root. March 2022. ↩
-
Scott O. Bradner. Key words for use in RFCs to Indicate Requirement Levels. RFC 2119, March 1997. URL: https://www.rfc-editor.org/info/rfc2119, doi:10.17487/RFC2119. ↩
-
The JSON data interchange syntax. ISO/IEC 21778, November 2017. URL: https://www.iso.org/standard/71616.html. ↩
-
Roger Barlow. Extended maximum likelihood. Nuclear Instruments and Methods in Physics Research Section A: Accelerators, Spectrometers, Detectors and Associated Equipment, 297(3):496–506, 1990. URL: https://www.sciencedirect.com/science/article/pii/0168900290913348, doi:https://doi.org/10.1016/0168-9002(90)91334-8. ↩↩
-
Glen Cowan, Kyle Cranmer, Eilam Gross, and Ofer Vitells. Asymptotic formulae for likelihood-based tests of new physics. Eur. Phys. J. C, 71:1554, 2011. [Erratum: Eur.Phys.J.C 73, 2501 (2013)]. arXiv:1007.1727, doi:10.1140/epjc/s10052-011-1554-0. ↩
-
R. L. Workman and Others. Review of Particle Physics. PTEP, 2022:083C01, 2022. doi:10.1093/ptep/ptac097. ↩↩↩
-
Kyle Cranmer, George Lewis, Lorenzo Moneta, Akira Shibata, and Wouter Verkerke. HistFactory: A tool for creating statistical models for use with RooFit and RooStats. Technical Report, New York U., New York, jan 2012. URL: https://cds.cern.ch/record/1456844, doi:10.17181/CERN-OPEN-2012-016. ↩
-
ATLAS Collaboration. Measurement of inclusive and differential cross sections in the $H \rightarrow ZZ^* \rightarrow 4\ell $ decay channel in \(pp\) collisions at \(\\sqrt s=13\) TeV with the ATLAS detector. JHEP, 10:132, 2017. arXiv:1708.02810, doi:10.1007/JHEP10(2017)132. ↩
-
Roger Barlow and Christine Beeston. Fitting using finite monte carlo samples. Computer Physics Communications, 77(2):219–228, 1993. URL: https://www.sciencedirect.com/science/article/pii/001046559390005W, doi:https://doi.org/10.1016/0010-4655(93)90005-W. ↩